What is a Query Bucket?
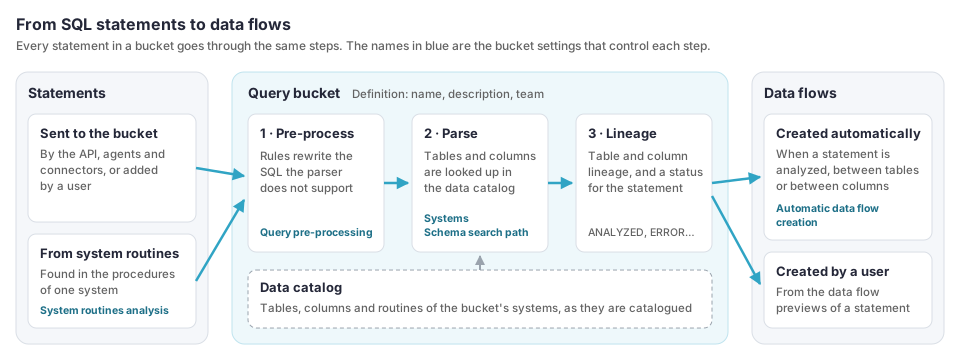
A query bucket groups SQL statements that are analyzed with the same settings. The bucket decides three things for each of its statements:
- which catalog to read: the systems whose tables and columns the statements use;
- how to prepare the SQL: rules that rewrite constructs the parser does not support;
- what to do with the result: whether data flows are created automatically, and at which level.
Statements reach a bucket through the API, agents and connectors, by hand, or from the routines of a system. Each one is pre-processed, parsed against the catalog and turned into lineage; from the lineage, Blindata creates data flows.
| Setting | What it controls | When it matters |
|---|---|---|
| Definition | Name, description and team of the bucket | always: the name is required |
| Systems | The catalog the parser reads | always: without the right systems, statements stay partially analyzed |
| Schema search path | Where tables written without a schema are looked for | statements use tables from more than one schema without naming it |
| Query pre-processing | How the SQL text is rewritten before parsing | statements end in ERROR because of dialect syntax |
| Automatic data flow creation | Whether and how data flows are created from analyzed statements | you trust the analysis enough to skip the review of each statement |
| System routines analysis | Which system’s routines feed the bucket, and how they are read | lineage comes from stored procedures or functions |
Bucket completion
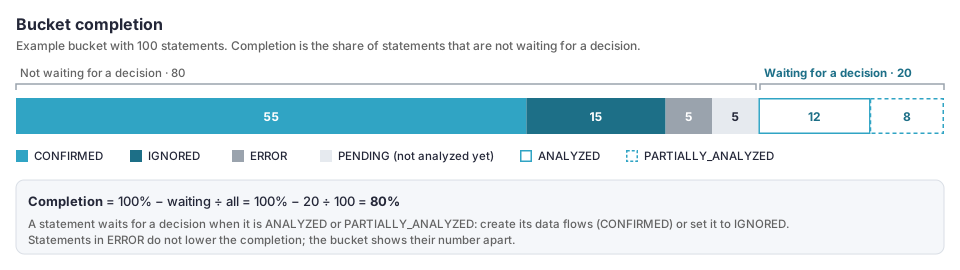
A bucket shows how many of its statements still wait for a decision. A statement waits for a decision when its analysis worked (ANALYZED or PARTIALLY_ANALYZED) but nobody has created its data flows or set it to IGNORED yet. The completion is the share of statements that are not waiting; the number of statements in ERROR is shown next to it.
Configure a Query Bucket
Buckets are created and edited in the Query parser section of Data flows. Only the name is required; the other settings have working defaults and can be changed later.
Note
Settings are used when a statement is analyzed. Changing them does not analyze again the statements already in the bucket: refresh them to apply the new settings.
Definition
- Name (required): unique among buckets.
- Description: what the bucket contains and where its statements come from.
- Team: the team the bucket belongs to.
Systems
The systems whose tables, columns and routines the statements use. The parser resolves each table of a statement only in the catalog of these systems. A table that is not found leaves the statement PARTIALLY_ANALYZED, and no data flow can reach or leave it.
Schema search path
A statement can name a table with its schema (sales.orders) or without it (orders). A table without a schema is looked for first in the statement’s default schema, then in each schema of the search path, from top to bottom; the first schema that has the table wins. Add schemas here when the statements use tables from more than one schema without naming it.
Query pre-processing
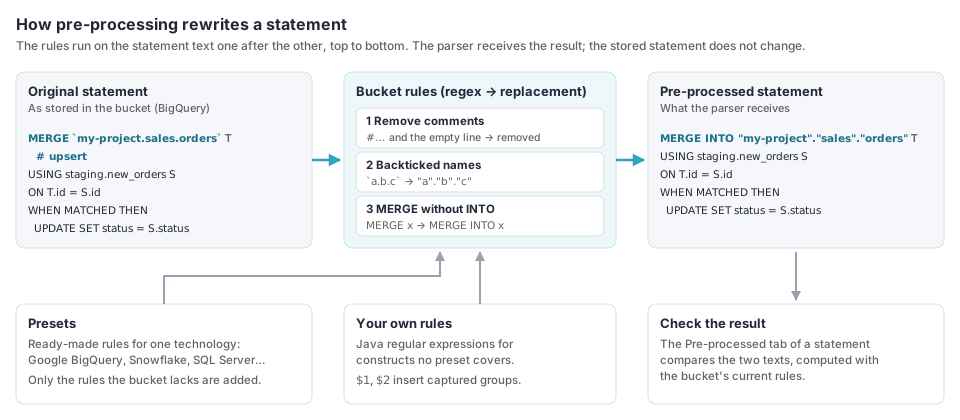
The parser does not support every SQL dialect. Pre-processing rewrites the text of each statement just before it is parsed, so that dialect syntax becomes SQL the parser understands, and statements that carry no lineage are set aside. The stored statement does not change.
How rules work
- A rule is a regular expression and a replacement, applied to the whole statement text like Java’s
String.replaceAll. In the replacement,$1,$2… insert the groups the expression captured; an empty replacement removes the match. - The rules run from top to bottom, each on the result of the previous one.
- The rules run at every analysis with the bucket’s current rules, including a refresh.
- A rule cannot contain
::::: Blindata stores the expression and the replacement joined by that separator.
Presets
A preset is a ready-made set of rules for one technology. Adding a preset adds only the rules the bucket does not already have, so adding it twice changes nothing and your own rules are kept. When one of the bucket’s systems uses a technology that has a preset, that preset is suggested. Rules that come from a preset keep its name in the bucket, so they stay distinguishable from your own.
| Preset | Technologies | What it covers |
|---|---|---|
| Common SQL | any | Comments, blank lines, a trailing comma before FROM. |
| Google BigQuery | Google BigQuery | The rules of the Google Dataform connector: see BigQuery query pre-processing . Do not combine it with other presets. |
| Snowflake | Snowflake | The common rules, TRANSIENT / SECURE, CLONE, COPY GRANTS and CLUSTER BY, semi-structured paths, named arguments, statements without lineage. |
| Microsoft SQL Server | SQL Server, Azure SQL, Azure Synapse | The common rules, GO lines, table hints (NOLOCK…), [bracket] identifiers, statements without lineage. |
| Oracle | Oracle | The common rules, SQL*Plus lines, / terminators, FORCE / EDITIONABLE views, storage clauses, statements without lineage. |
| AWS Redshift | AWS Redshift | The common rules, DISTKEY / SORTKEY / ENCODE, statements without lineage. |
| Databricks | Databricks, Databricks Unity Catalog | Comments, backticked names, Delta table options, temporary views, CLONE, INSERT OVERWRITE, statements without lineage. Do not combine it with Common SQL. |
Info
Presets are a starting point. The Google BigQuery preset is the set the Dataform connector uses on real projects; the other presets have been checked on sample statements only. After adding one, check some statements in ERROR or PARTIALLY_ANALYZED status (see Check the result
) and adjust the rules if needed.
Statements without lineage
Some statements produce no lineage: ALTER, GRANT, CALL, COPY INTO and similar. Left as they are, the parser often rejects them and they end in ERROR. The presets rewrite them into a statement the parser ignores, so their status is IGNORED and the errors left in the bucket are the ones worth looking at.
Write your own rules
When no preset covers a construct, add a rule for it.
- Make each rule independent of the others. A rule that only works after another one breaks when the rules are reordered or a preset adds rules after it. The preset rules are written to give the same result in any order.
- Match only what you need. The rules apply to every statement in the bucket, including those that already parse.
- Avoid expressions that can backtrack for a long time, such as nested repetitions (
(a+)+). Rule application has no time limit, and a long statement can block its analysis. Possessive quantifiers (*+,++) prevent it. - Keep preset rules unchanged. A preset rule that you edit becomes one of your own rules, and adding the preset again adds the original back.
Check the result
When a bucket has pre-processing rules, a statement’s Query section has two tabs: Original, the statement as stored, and Pre-processed, a side-by-side comparison of the original with the text the parser receives. The comparison uses the bucket’s current rules, so after a change to the rules it can differ from what the last analysis used until the statement is refreshed.
BigQuery query pre-processing
BigQuery SQL has constructs that the statement parser does not support. The Google BigQuery preset has 32 rules that rewrite them, written to give the same result in any order.
| Group | What the rules do |
|---|---|
| Comments and blank lines | Remove --, # and /* */ comments outside quoted text, and the blank lines that comments or the Dataform config block leave. Remove a trailing comma before FROM. |
| Names | Turn backticked names (`project.dataset.table`) into quoted names, and remove a hyphenated project ID from unquoted names. |
MERGE and DELETE |
Accept MERGE without INTO, WHEN NOT MATCHED BY TARGET and BY SOURCE, and DELETE without FROM. |
| Expressions and literals | Handle BIGNUMERIC and INTERVAL … HOUR TO MINUTE literals, named arguments (name => value), TABLE / MODEL arguments, FOR SYSTEM_TIME AS OF, UNNEST … WITH OFFSET, a field read after an array subscript, struct.*, pseudo-columns such as _TABLE_SUFFIX, and SELECT WITH DIFFERENTIAL_PRIVACY. |
| Table definitions | Handle ARRAY<…> / STRUCT<…> column types, NOT ENFORCED, OPTIONS (…), and PARTITION BY with an expression. |
| Statements with a different shape | Read CREATE TABLE … COPY / CLONE, CREATE TABLE FUNCTION, EXPORT DATA … AS SELECT, CREATE MODEL … AS SELECT and ASSERT through the query they contain. |
| Statements without lineage | CREATE FUNCTION / PROCEDURE, CREATE SCHEMA, ALTER, CALL, EXECUTE IMMEDIATE, LOAD DATA, GRANT and REVOKE end as IGNORED. |
Still not supported by the parser, with or without the preset: MERGE … WHEN NOT MATCHED THEN INSERT ROW, strings with escaped quotes, triple-quoted strings, UNION … BY NAME, and CREATE VIEW with a column list.
Note
Query buckets for Google Dataform are created and configured by the Dataform job, one for each repository environment, with these 32 rules. Do not create them by hand: the job rewrites their rules on its next run. See Data lineage in the Google Dataform connector.
Automatic data flow creation
By default, data flows are created only when a user confirms the previews of a statement (see Dataflow creation strategies ). The bucket can instead create them as soon as a statement is analyzed.
| Strategy | Data flows created automatically |
|---|---|
| No strategy defined | none: data flows are created from the previews only |
| Entity | between physical entities (table to table) |
| Field | between physical fields (column to column) |
The lineage of a statement has two kinds of relation between columns:
- FDD (from data to data): the data of the target column comes directly from the source column. In
SELECT a.empName "eName" FROM scott.emp a, the columneNamecomes fromscott.emp.empName. - FDR (from data to rows): the data of the source column affects the number of rows of the result, or the result of an aggregate function. In
SELECT a.empName "eName" FROM scott.emp a WHERE sal > 1000, the values ofsaldecide which rows the result has.
Data flows are created from FDD relations only. Enable Create FDR data flows to create them from FDR relations too; it is off by default.
System routines analysis
A bucket can collect the statements of the stored procedures and functions of one system, and analyze them again each time a routine is created or changed.
- System: the system whose routines feed the bucket.
- Analysis strategy:
- Automatic: the statements are found in the routine body and analyzed.
- Markup: only the statements marked with annotations in the routine body are analyzed. See Analyze SQL Script or Routines .
- Disable system routines temporary tables: by default, the tables a routine creates are used, together with the catalog, to analyze the routine’s other statements. Enable it to use only the tables in the catalog.
- Disable table-valued functions: when enabled, table-valued functions in the bucket’s statements are not resolved against the system routines, and their bodies are not part of the lineage. Leave it off unless a wrong match pollutes the results. See Table-valued functions in SQL Lineage .
Statement Analysis
A SQL statement is analyzed in order to reconstruct the Lineage which it creates. From Lineage it is possible to extract DataFlow. Thanks to overall saved DataFlow you can trace the data lineage of the entire system. A Statement is analyzed by Parser when this is inserted inside a Bucket or when the text of the SQL statement is modified.
A Statement can have one of the following status:
| Statement State | Description |
|---|---|
| PENDING | Statement must still be analyzed by Parser. |
| ANALYZED | The parser was able to correctly analyze the statement and to recover from the catalog all tables and table-valued functions used inside it. |
| PARTIALLY_ANALYZED | The parser was able to correctly analyze the statement but could not recover every catalog object it needs: missing tables or columns, or table-valued functions that could not be resolved to a unique analyzed system routine. |
| ERROR | The parser was unable to properly analyze the Statement due to a syntax error in the SQL statement or an error in the analysis. |
| IGNORE | The Statement will not be reviewed by the system. The Statement can be put in this state as a result of an user’s action or a submission of a Statement that however led to the same result as the one produced by another statement. |
| CONFIRMED | One or more DataFlows were generated using the Statement. Once the Statement is in this state, it will no longer be reanalyzed. |
If the Statement is in the ANALYZED or PARTIALLY_ANALYZED status, it is indicated in the field “type” even the type of SQL statement that the Parser was able to recognise.
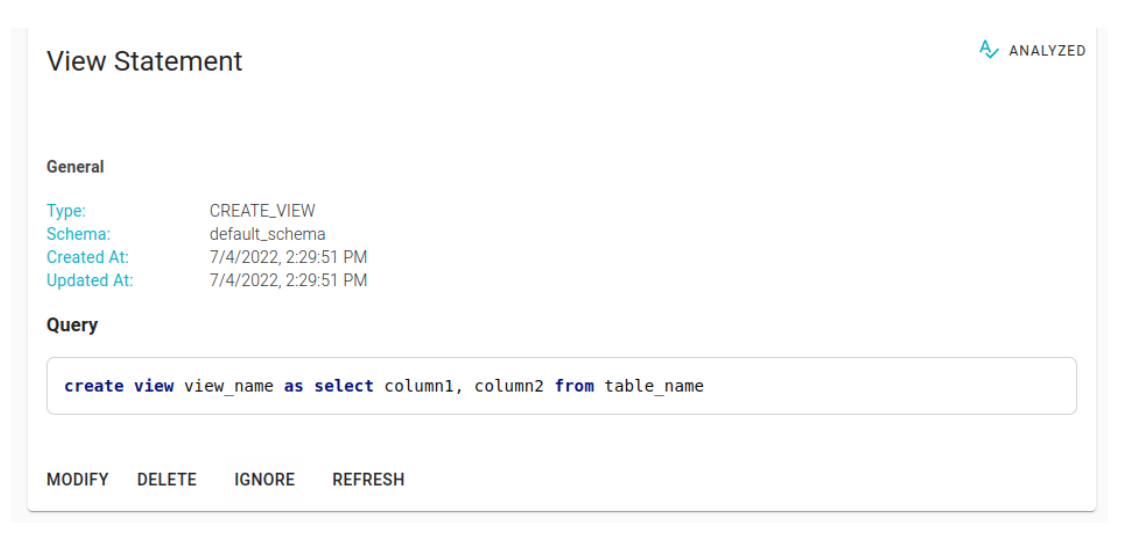
Using the refresh button on the Statement detail page, it is possible to re-analyze it regardless of the state in which it is located (except for a Statement of SELECT or SELECT_INTO which has been linked to a target table).
Target destination of a select statement
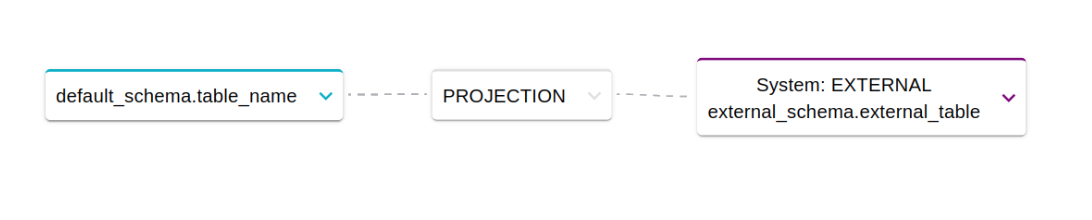
An entity in a system may have been generated from data in another system. If extraction is done using a SQL statement , it is possible to represent this link connecting to a SQL statement of SELECT with a target table outside the system. Every time that a SELECT Statement is correctly analyzed by Parser ( ANALYZED o PARTIALLY_ANALYZED status), it is shown a warning with a button that refers to a modal for the link with a target table.
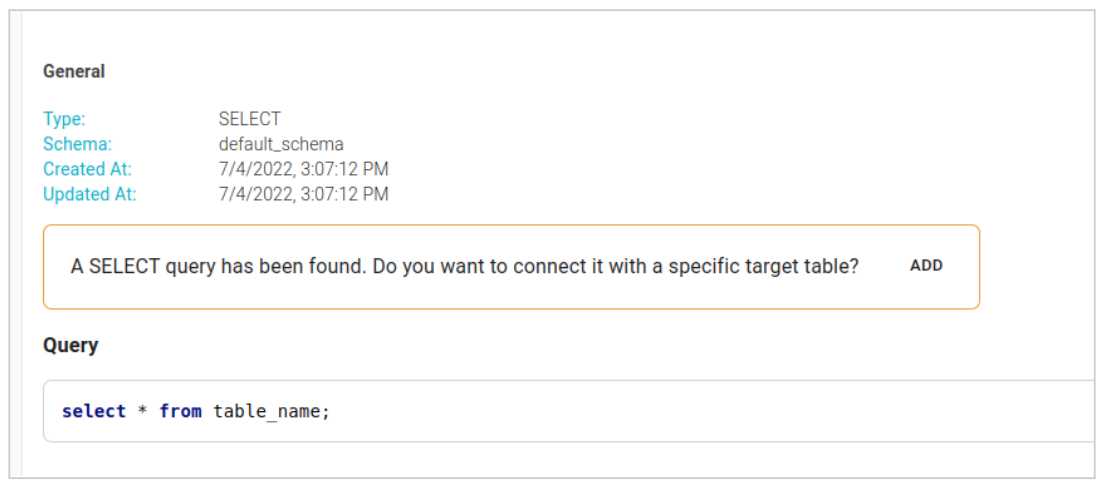
From modal it is possible to choose the target table among the Physical Entities.
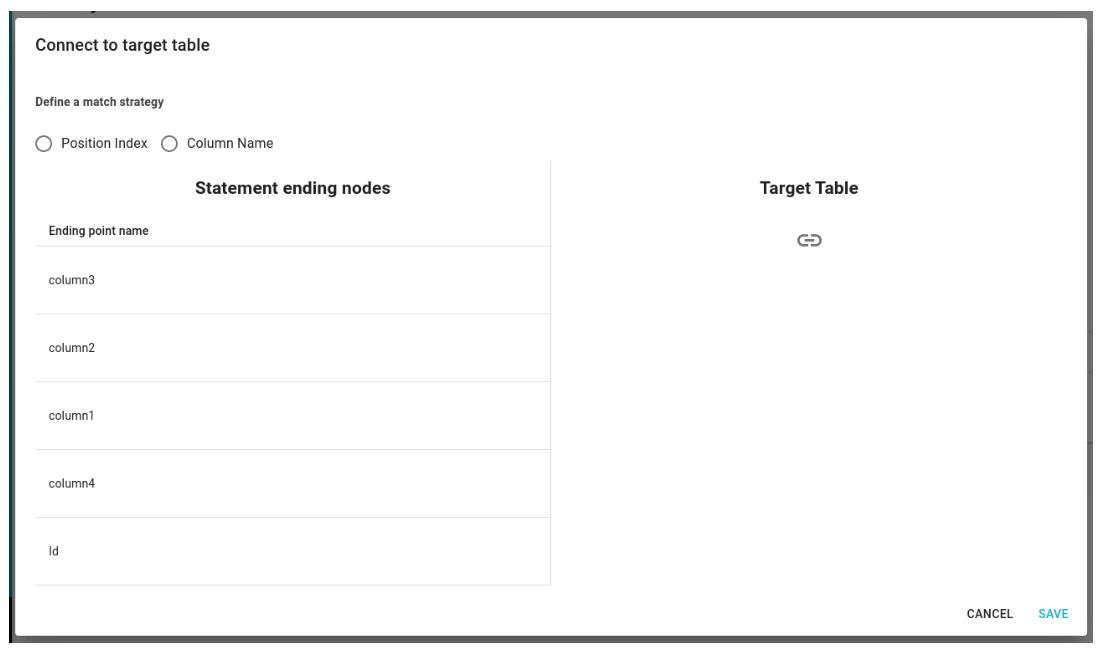
You can then connect the output of the SQL statement with Physical Fields of target table through:
- Column number
- Index number of the column.
- Choosing by hand the Physical Field.
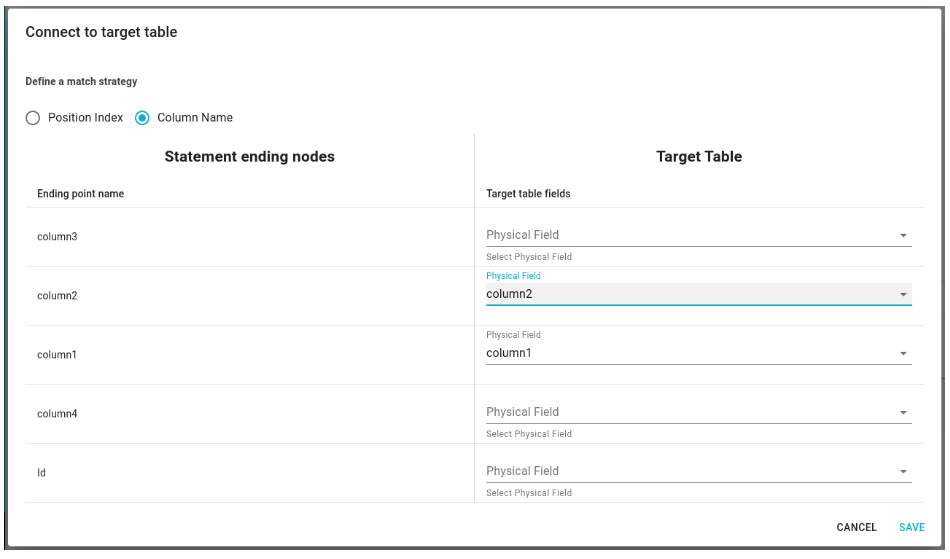
Once the table is connected the lineage is updated and it is possible to generate the related DataFlows.
Lineage between entity not involved in SQL statements
An entity in a system may have been imported from another system without using SQL statements (e.g. dump csv, file transfer, job of etl). In this case, a link between two Physical Entities is represented through or a single DataFlow, or a set of DataFlows between their Physical Fields. To generate the DataFlow simply go to the detail page of one of the two Physical Entities and access the section dedicated to DataFlows.
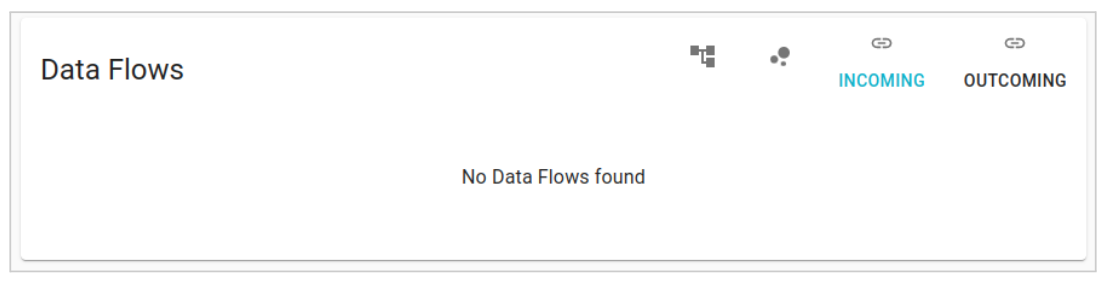
From here then to establish the direction of the connection one of the two icons located above the buttons must be selected “INCOMING” and “OUTCOMING”. These open a modal, by which you can choose the connection level (a single DataFlow between the two Physical Entities or more DataFlow between their Physical Fields).
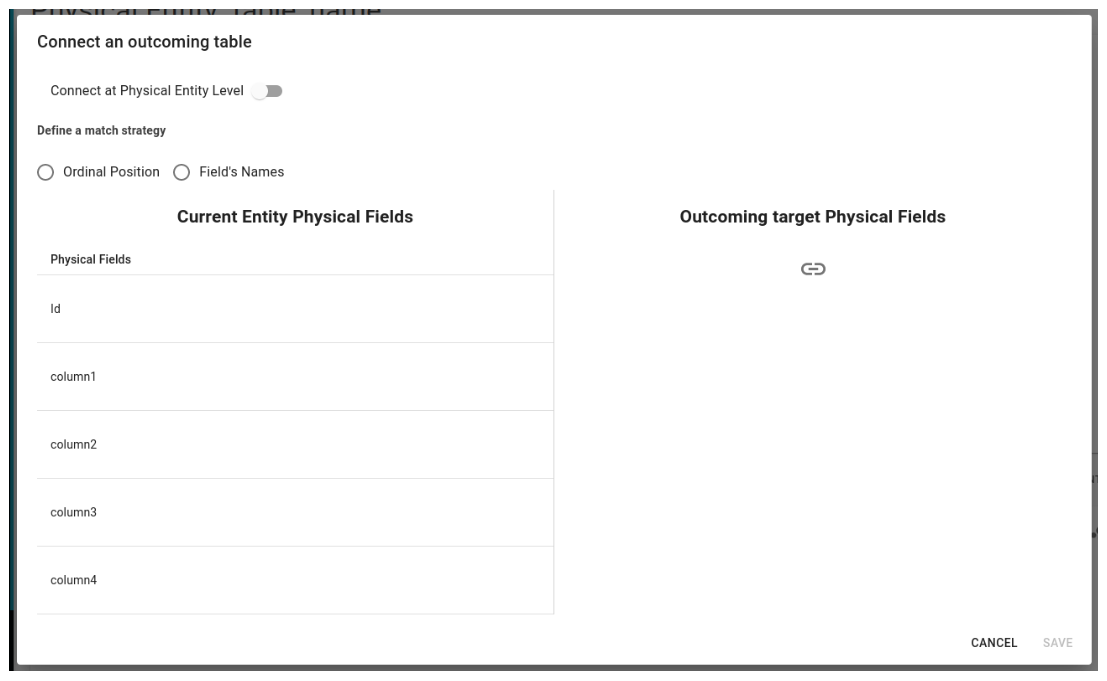
If it is chosen the link at Physical Fields level, DataFlows can be generated using two different strategies:
- Through Ordinal Position of Physical Fields.
- Through Column Name of Physical Fields.
Finally, there is always the possibility to manually choose individual links between fields.
Dataflow creation strategies
Once the Parser has managed to extract the Lineage from a Statement, the data lineage information can be saved within the data catalog through the DataFlows.
When the statement calls a catalogued table-valued function, Full Lineage (and therefore data flow previews) includes the function body: source tables inside the function can appear as origins of the caller’s data flows. See Table-valued functions in SQL Lineage .
Starting from a Statement it is possible to generate DataFlows, if the following conditions are satisfied:
- Statement’s status is ANALYZED or PARTIALLY_ANALYZED.
- The starting Physical Entity and target Physical Entity are inside the catalog.
- The Lineage obtained from the analysis of the Statement contains at least one path between the source Physical Entity and the destination one.
Creation can be either manual or automated:
| Strategy | Description |
|---|---|
| Manual creation of Dataflows | In order to create a DataFlow manually you need to go to the “Data Flows Preview” section on the Statement’s detail page. Here, a list of all the DataFlow previews that can be generated starting from the analyzed Statement will be shown. Previews are calculated either at the level of Physical Fields or at the level of Physical Entities. 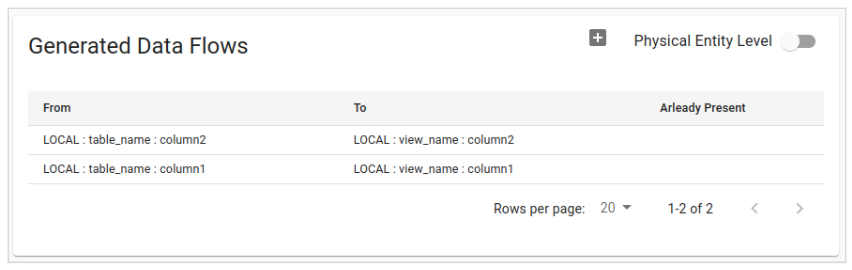 This behavior can be selected via the “Physical Entity Level” switch. To save the previews, just click on the appropriate add button and confirm. Previews that generated DataFlow are indicated with a blue check. |
| Automatic creation | It is possible to create DataFlows at the same time as inserting a new Statement inside a Bucket. This feature can be enabled in the Bucket settings by editing the “Automatic DataFlow Creation’’ items. 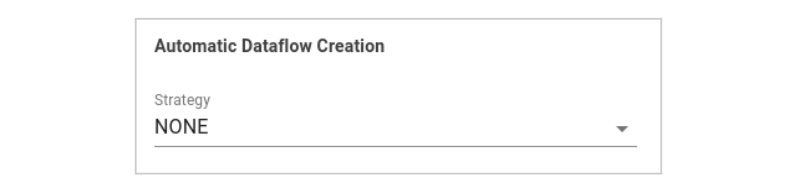 As with manual generation, it is possible to choose whether to generate DataFlows at the level of Physical Entities or at the level of Physical Fields. |
Refreshing Statements analysis
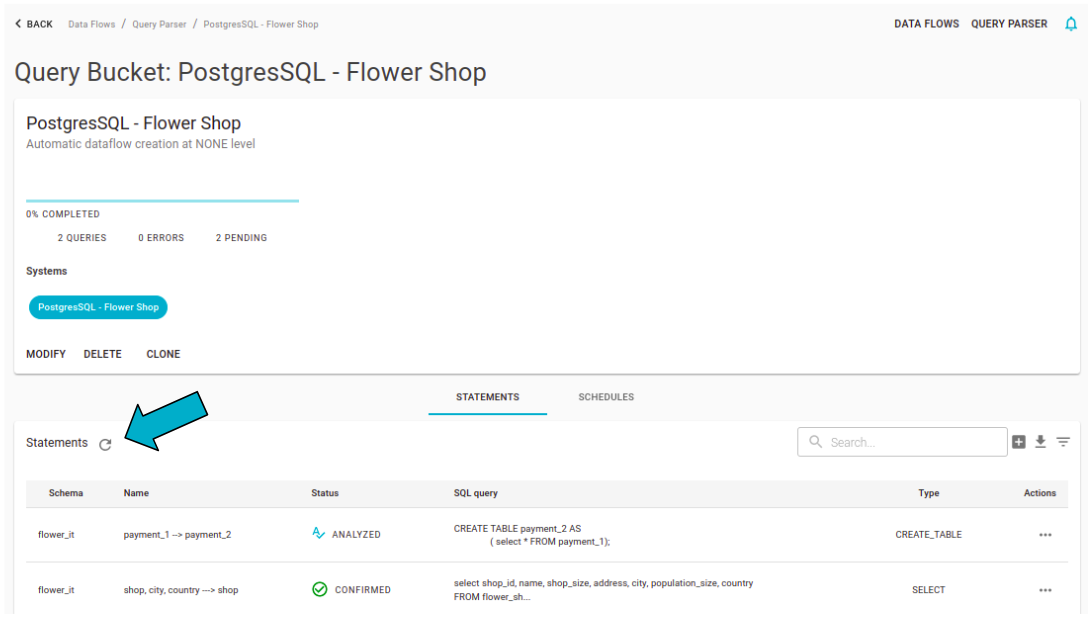
The refresh operation allows you to reset the operations performed on the statement and rerun the analysis. This includes deleting dataflows and removing any associated target tables (for select statements). The operations performed during the refresh are as follows:
- rollback and deletion of created dataflows
- deletion of full lineage data
- parsing the statement and generating a new full lineage
- automatic data flow creation if enabled on the bucket
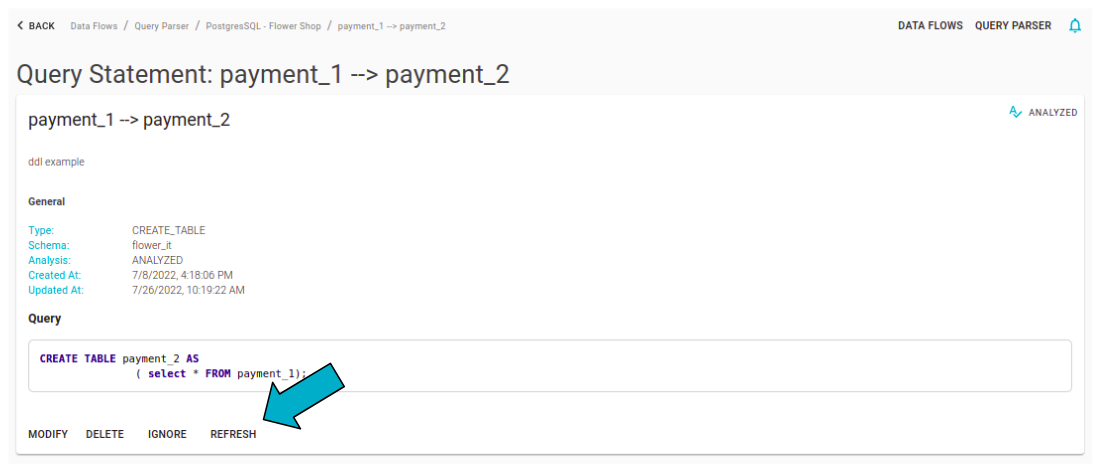
On the detail page of a Bucket it is possible to apply a massive refresh to all the statements it contains. The procedure can take several minutes to complete: it is necessary to keep the application open.
Lineage Visualization
The Lineage can be viewed on the Statement detail page, in the “Full Lineage” section. It is available only in the case of a positive analysis (ANALYZED or PARTIALLY_ANALYZED status).
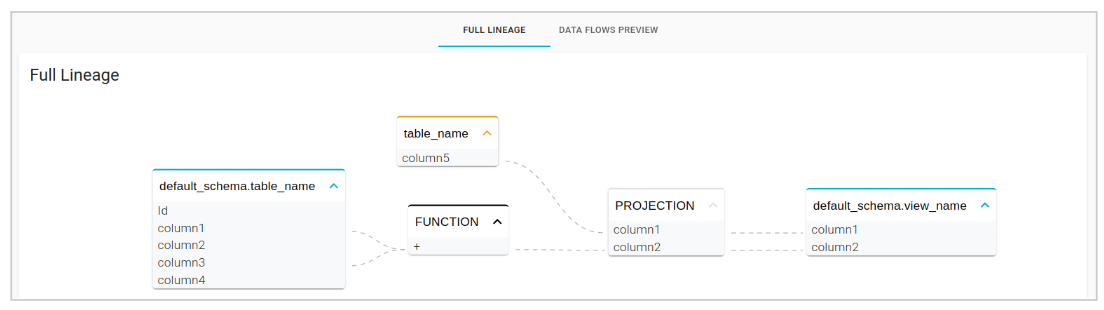
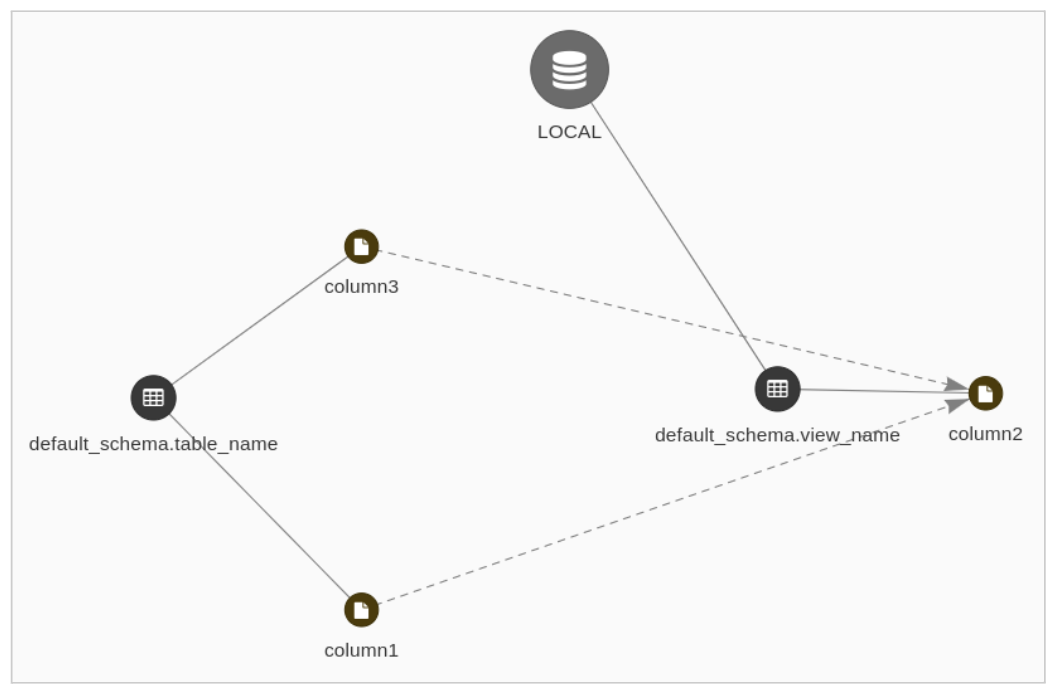
Nodes in the chart:
- Blue: columns found in the data catalog, grouped by table.
- Orange: objects not found in the catalog — missing tables, or unresolved table-valued functions.
- Purple: a resolved table-valued function, bound to a system routine. Right-click the node and open Name to jump to that routine.
When the same function is called more than once in one statement, each call stays a separate node. How to catalog a function so it resolves — including crawl SQL, parameters, and the bucket checkbox Disable table-valued functions — is in Table-valued functions in SQL Lineage .
The visualization of the complete data lineage is located in the “Data Flows” sub-section of the Physical Entities detail page.
You can choose whether to view the data lineage via flow chart
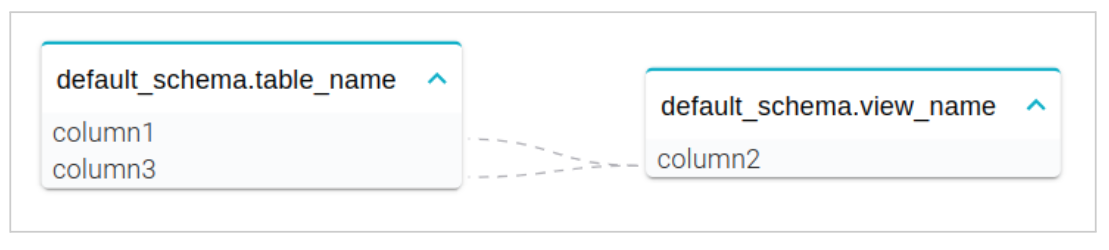 or via graph.